Tech Corner
Ultimate Cheatsheet to tune your Hyper-Parameters in ML Algorithms
Looking for a cheatsheet to tune your Hyper-Parameters in Machine Learning and Neural Network Algorithms? We've got you covered! Click here to learn more.
The bounding box, usually abbreviated as bbox is an area defined by two longitudes and two latitudes where the latitude is a decimal number between -90.0 and 90.0 and the longitude is a decimal number between -180.0 and 180.0.
They usually follow this standard format:
bbox = left,bottom,right,top
bbox = min Longitude , min Latitude , max Longitude , max Latitude
A bounding box is essentially a rectangle that surrounds an object and specifies its location, class (for example, car or person), and confidence (the likelihood of it being in that location).
A bounding box is primarily utilized for the task of object detection. Here the goal is to identify the position and type of several objects in an image.
You could say that the bounding box is an abstract rectangle that serves as a reference point for object detection and generates a collision box for that object. These rectangles get drawn over images by data annotators, who identify the X and Y coordinates of the point of interest inside every image. This assists machine learning algorithms in finding what they are searching for, evaluating collision paths, and even helps in saving computational power.
Bounding boxes are among the most widely used image annotation techniques in deep learning. The bounding box technique can save resources and improve annotation performance substantially in comparison with other image processing approaches.
In fact, the bounding box technique is one of the least costly and time-consuming annotation approaches that you could use.
While specifying a bounding box, there are two main conventions that tend to be followed. These main conventions are mentioned below:
Let’s take an example of a car to understand these conventions.
Following the first convention, the bounding box would be specified according to the coordinates of the top left point and the bottom right point.
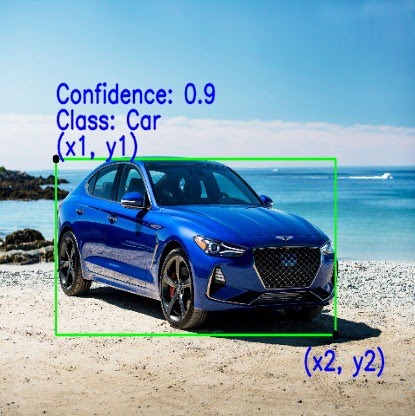
Following the first convention, the bounding box would be specified according to its center, width, and height.
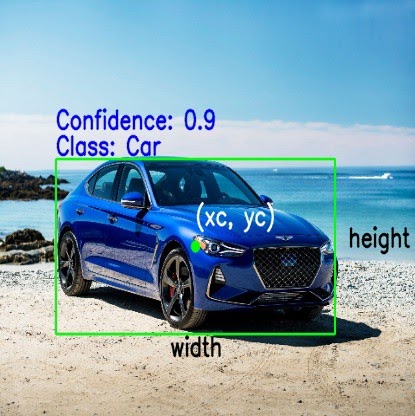
The parameters used are dependent on the convention that is being used to specify the bounding box. Here are the main parameters that are used:
It is possible to convert between the different forms of representing the bounding box, depending on your use case.
The bounding box helps computers know what an object is and where it is to detect it in an image. As an example, autonomous vehicles would number other vehicles and have a bounding box drawn around them by an annotator. This aids in the preparation of an algorithm to identify various types of vehicles.
This enables self-driving vehicles to drive through busy streets by annotating items such as vehicles, traffic signals, and pedestrians. Perception models have a heavy dependence on the bounding boxes to make this happen.
However, a single bounding box doesn’t guarantee a flawless prediction quality. For enhanced target tracking, you need a vast range of bounding frames, and data augmentation techniques.
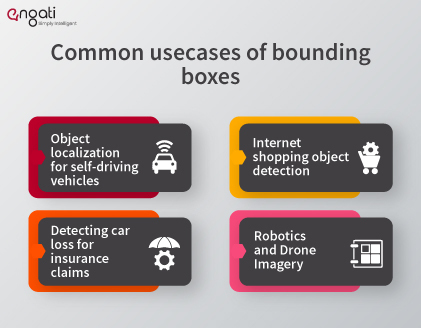
The bounding boxes are generally used to train autonomous vehicle vision models to identify different types of artifacts on the road, such as traffic signals, lane barriers, and pedestrians, among other items. Both identifiable obstacles can be easily annotated using bounding boxes to enable robots to recognize their environments and drive the car in a safe manner and prevent collisions, even when driving on congested streets.
Products sold online are also annotated with bounding boxes to recall what clothing or other accessories buyers are wearing. This technique can be used to annotate all forms of fashion accessories, enabling visual search machine learning models to identify them and provide additional knowledge to end-users.
It is possible to track types of vehicles like cars and bikes that have been damaged in an accident by making use of bounding box annotated images. ML models can use bounding boxes to learn the intensity and position of losses to predict the cost of lawsuits so that a client can provide an estimate before making a lawsuit.
Image annotation is widely used to mark items from the viewpoint of robots and drones. Autonomous vehicles like robots and drones can classify several objects on the planet by making use of photographs annotated with this technique.
Tech Corner
Looking for a cheatsheet to tune your Hyper-Parameters in Machine Learning and Neural Network Algorithms? We've got you covered! Click here to learn more.
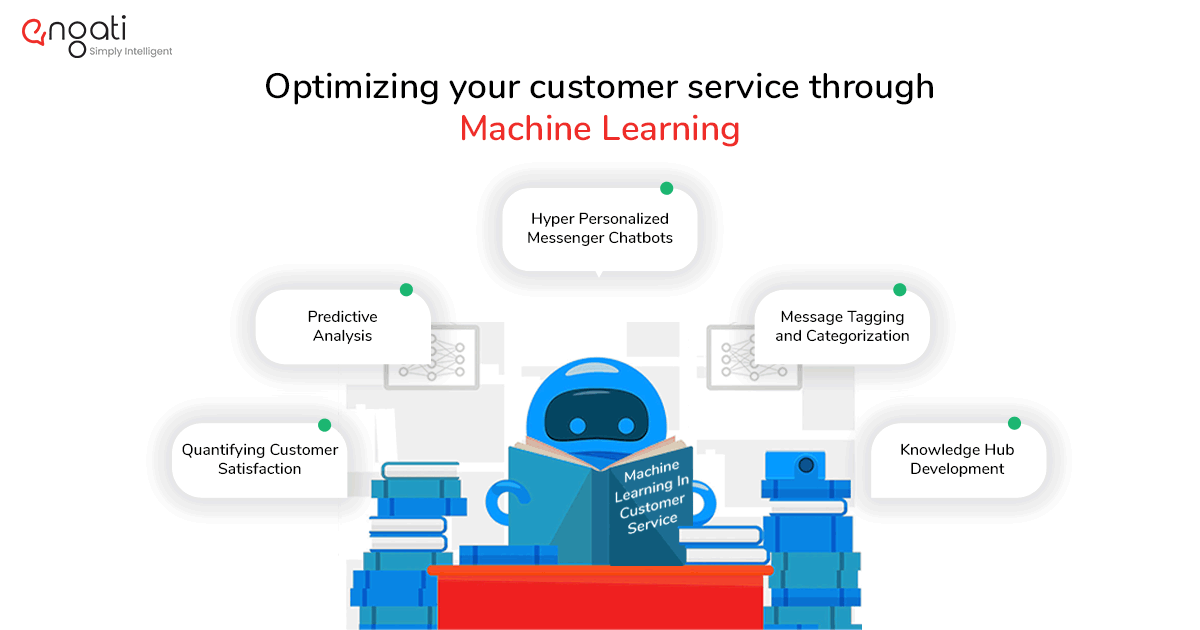
Future of CX
The use of machine learning is increasing as businesses explore new ways to optimize customer service. Here are a couple of ways to use it in your business.
Tech Corner
In this blog, we’ll see what machine learning is all about. How is it growing big globally. How are businesses stepping up their game with machine learning.